Wan 3.0 Text to video API

alibaba / 3.0

Wan 3.0 creates 2-30 second videos from text, first and last frames, or multimodal references, and edits source videos with native sound.

Choose text, frame, reference, or editing mode. Set the resolution and framing; generation modes let you select output length, while video-edit follows the source duration.

Pricing

Output resolution

Text-to-video and image-to-video use only output duration. Reference-to-video uses the combined reference-video and output duration: 5 seconds of reference video plus 10 seconds of output totals 15 seconds. Video editing preserves the source duration, so a 5-second source totals 10 seconds of usage. All modes use the selected resolution rate.

480p
$0.04/s
720p
$0.08/s
1080p
$0.16/s
Input

Prompt, assets, and output parameters form one generation request.

Describe the scene, action, camera movement, and sound. Maximum 20,000 characters.
Aspect ratioChoose automatic framing or a fixed landscape, square, or portrait frame.
ResolutionChoose 480p, 720p, or 1080p output.
Video durationChoose a whole-number output length from 2 to 30 seconds.
5s

Model overview

Wan 3.0 text, image, and reference video generator and API

Wan 3.0 on sjolt supports text-to-video, image-to-video, reference-to-video, and video-edit workflows. Start from a written scene, animate a required first frame with an optional last frame, coordinate images, MP4 clips, and audio references, or edit one source video at its original duration. Retrieve the completed MP4 through the shared asynchronous task API.

Wan 3.0 generation example
01 · Video generation

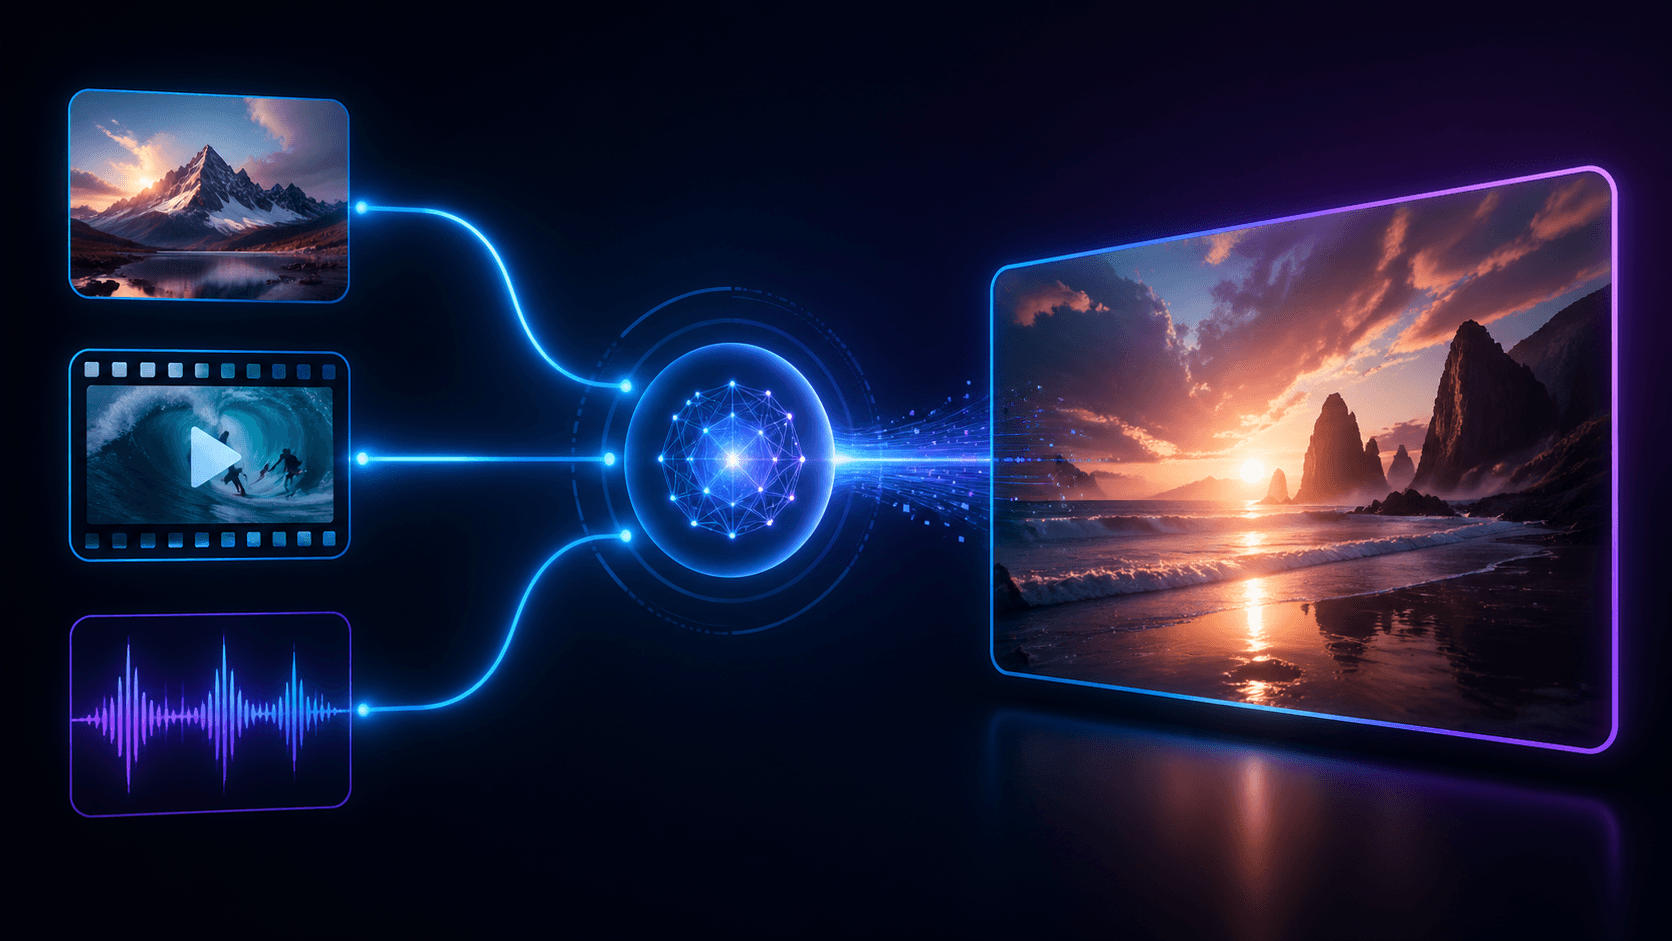
Coordinate image, motion, and audio references

Combine up to 10 images and 5 audio tracks with up to 5 MP4 references in reference-to-video, or exactly one source video in video-edit. Assign every asset a clear role with @ mentions so subjects, visual language, camera movement, timing, dialogue, ambience, or music remain easy to interpret.

  • Supports Text to video and reference-asset generation workflows.
  • Fits product assets, ad previews, visual direction, and social content tests.
  • Adjust configured inputs, media, and switches before generation.
Reference asset control example
02 · Asset control

Direct motion and sound as one scene

Describe the opening state, subject action, camera path, environmental response, sound cues, and intended ending. Use concise temporal language to align visible events with dialogue, effects, ambience, or musical beats.

Prompt-led generation
Unified model API and result management example
03 · API integration

Flexible framing and asynchronous delivery

Use adaptive framing or choose 16:9, 9:16, 1:1, 4:3, 3:4, and select 480p, 720p, or 1080p. Text, image, and reference generation accept a whole-number output length from 2 to 30 seconds; video-edit automatically matches the source length. Submit once, then poll the task identifier or receive a webhook when the video is ready.

  • Compare available models from Alibaba, Black Forest Labs, Google, MiniMax, Midjourney, OpenAI, ByteDance, Kuaishou, SJolt AI, Suno, xAI in one place.
  • Copy the request body directly to the server to reduce frontend/backend parameter drift.
  • Failure states, retries, result preview, and review checkpoints stay in the same workflow.

Model characteristics

Direct scenes through written prompts, frame control, references, and editing.

01

Text and frame direction

Generate a scene from a written prompt, or animate a first frame with an optional last frame. Frame-guided generation accepts optional instructions and uses the supplied images as the actual opening and ending frames.

02

Multimodal reference control

Use images for identity and composition, videos for motion and camera rhythm, and audio for dialogue, effects, ambience, or music direction.

03

Optional prompt direction

Generate from references alone or add a written production brief with explicit @ mentions for each uploaded asset.

04

Flexible delivery formats

Choose adaptive framing or 16:9, 9:16, 1:1, 4:3, 3:4 and output from 480p through 1080p. Text, image, and reference generation offer 2–30 seconds; video-edit preserves the source duration.

05

Unified task workflow

Use the provider-qualified route for your chosen workflow, the shared task-status endpoint, and optional webhook delivery for repeatable production pipelines.

FAQ

These are the first questions to answer when evaluating this model.

Which Wan 3.0 workflows are available on sjolt?

Choose text-to-video for a written scene, image-to-video for a required first frame and optional last frame, reference-to-video for image, video, or audio guidance, and video-edit to edit exactly one source video at its original duration.

How do first and last frames work?

Image-to-video requires a first-frame PNG, JPG, JPEG, or WebP image and accepts an optional last-frame image. Add instructions if needed, or generate from the frames alone. Auto framing follows the first frame.

Which reference files can I upload?

Upload up to 10 PNG, JPG, JPEG, or WebP images and 5 MP3, WAV, M4A, AAC, or OGG audio tracks. Reference-to-video accepts up to 5 MP4 clips and requires at least one reference asset; video-edit requires exactly one MP4 clip.

What are the media duration limits?

Reference videos may total at most 15 seconds, reference audio may total at most 15 seconds, and reference-video length plus output length cannot exceed 30 seconds.

Is a prompt required?

Text-to-video requires a non-empty prompt. Image-to-video, reference-to-video, and video-edit accept optional instructions. In reference and editing modes, mention each asset as @Image, @Video, or @Audio and describe its intended role.

Which output settings are available?

Choose adaptive framing or 16:9, 9:16, 1:1, 4:3, 3:4, and 480p, 720p, or 1080p. Text, image, and reference generation accept a whole-number duration from 2 to 30 seconds. Video-edit automatically matches the source video duration.

How does the API workflow work?

Submit the provider-qualified route for text-to-video, image-to-video, reference-to-video, or video-edit, keep the returned task identifier, then poll the shared task endpoint or receive a webhook. Successful tasks return the generated MP4 URL.